
AI Agent Data Leakage: Catch the Read, Then the Send
Most AI agent data leakage needs two steps. First the agent reads something it should keep: a production config, a customer record, a secret in an internal wiki. Later, in the same session, it sends data somewhere you don't control. Either step alone is ordinary work. Together they are how data walks out. As of today, Autonomous Security watches for that pair in every session of your AI agents, and flags it, or blocks the send when you turn on enforcement.
Why AI agent data leakage is hard to catch
A coding agent with a terminal is useful because it can do three things at once: read private data, take in content you didn't write, and talk to the network. A README in a dependency, an issue comment or a web page can carry instructions, and an agent that follows them still has everything it read earlier in the session.
Classic DLP looks at one transfer at a time. An agent session is a chain: hundreds of tool calls, each one harmless on its own. The upload at the end looks like any other upload, and the read an hour earlier looks like any other read. What matters is the order.
We wrote about this on our own infrastructure in Restricting AI agents when no human is watching: once a session touches something sensitive, where it may send data has to change. That idea is now a product feature for everyone's agents, attended or not.
An example
A developer asks their agent to find out why a deploy keeps failing. The agent opens the deployment's configuration from an internal system, and with it a database password. To check a theory, it follows a troubleshooting step from a forum thread that says to paste the full config into an online "validator". The agent runs a command that posts the file to a site nobody at the company has heard of.
Nothing in that session was malicious on its face. A developer watching closely might have caught it. Most don't watch every tool call, and a background agent has nobody watching at all.
What session data-leakage protection does
You tell Autonomous two things: which sources are sensitive, and which destinations you trust.
- Sensitive sources are the systems whose data must not leave: internal domains, a code host, a cloud account. Autonomous suggests candidates from what your agents already touch, so you start from real traffic rather than a blank list.
- Trusted destinations are where data may go: your own domains, your GitHub organizations, your cloud accounts. A push to your own organization is normal work, not a leak. A push to a personal account is not.
From then on, a session that has read from a sensitive source is watched for the rest of its life. When it later tries to send data to a destination outside your trusted list, that send is what counts:
- Monitor (the default) records it and marks the session, so you can see the pattern before you act on it.
- Enforce blocks the send on the AI agents that support blocking, while the agent goes on working. It can keep reading, editing and running tests. It just can't send that data somewhere you didn't approve.
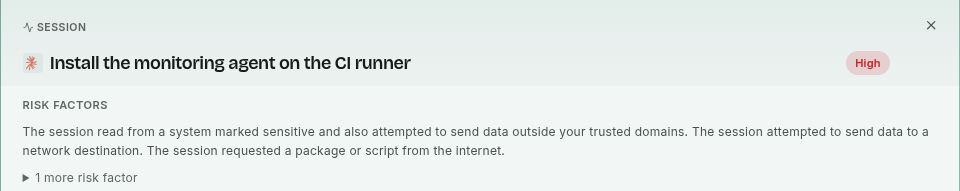
In Activity, those sessions carry a Data leakage signal, and a filter lists every session where a sensitive read and an attempted outside send happened together. The risk factors say it in plain words: the session read from a system marked sensitive, then tried to send data outside your trusted domains.
Broad or intelligent analysis
Added on October 4, 2026.
Some teams want every untrusted send after a sensitive read in front of them. Others run agents that legitimately call many outside services, and want only the sends that carry data out. You now choose which sessions the Data leakage signal flags:
- Broad, the default: any send to an untrusted destination after a sensitive read.
- Intelligent: only a later command that visibly carries data to an untrusted destination, such as an upload
with
curl.
In the example above, both flag the upload to the "validator". Intelligent is for the teams whose agents talk to many outside services in the course of normal work, and who want the signal kept for the sends that carry data.
Where to start
- Mark the two or three systems you would least like to see in someone else's hands. Take the suggestions as a starting point.
- Add your company domains and code organizations as trusted destinations, so normal pushes stay quiet.
- Run in Monitor for a week and read the flagged sessions.
- Turn on Enforce when what is flagged is what you would have stopped.
The protection follows the agent session, so it covers the commands and tool calls the agent makes in it. For the model traffic that goes through your own LLM gateway, there is a separate layer: guardrails that mask secrets and block unsafe calls on the LiteLLM proxy you run.
Try it
AI agents are going to read sensitive data; that is the job. The question is where it can go next. If your developers run Claude Code, Cursor or Codex, start a free trial, mark your sensitive systems, and see which of last week's sessions would have been flagged.
Related posts
AI Security in Your SOC: API, Webhook and IBM QRadar
Scoped API keys, a findings API and webhook in beta, and an IBM QRadar integration bring AI agent findings and audit logs into the tools your SOC already uses.
Read More
Block Personal AI Accounts and Unapproved AI Apps
Block prompts from personal and unapproved AI accounts, stop disallowed AI apps on Windows, macOS and Linux, and see what was blocked on the Enforcement page.
Read More
AI Security Posture Score and Automated Investigations
One AI security posture score for your fleet, a risk worklist that drives it, and AI-written investigations of risky agent sessions, in our redesigned console.
Read More